CSV Reader
The CSV Reader reads a character-separated text file as a data source. Commas are the common case and the name, but the delimiter is a setting: pipes, tabs and multi-character separators are read the same way.
The file does not have to be on disk. The reader takes its data from an IO controller, so the same transform can pick a file up from a folder, download one over HTTP, or take one off an email.
It also reads hierarchical files, where one file holds headers, details and sub-details. See Hierarchical data below.
Example
A flat CSV file has one record per line and the same fields on every line. A field can be empty, but it still sits between its two delimiters:
OrderId,OrderType,Currency,CustomerFirstName,CustomerLastName,Email,City,Country,Postcode
FBRN-309242,Web,USD,Ronald,English,[email protected],Fairbanks,USA,79160
FBRN-309243,Web,GBP,Claire,Ward,[email protected],London,United Kingdom,E3 4RR
Setup
The Setup tab carries the transform's identity, the source the file comes from, and the options that say how to read it.
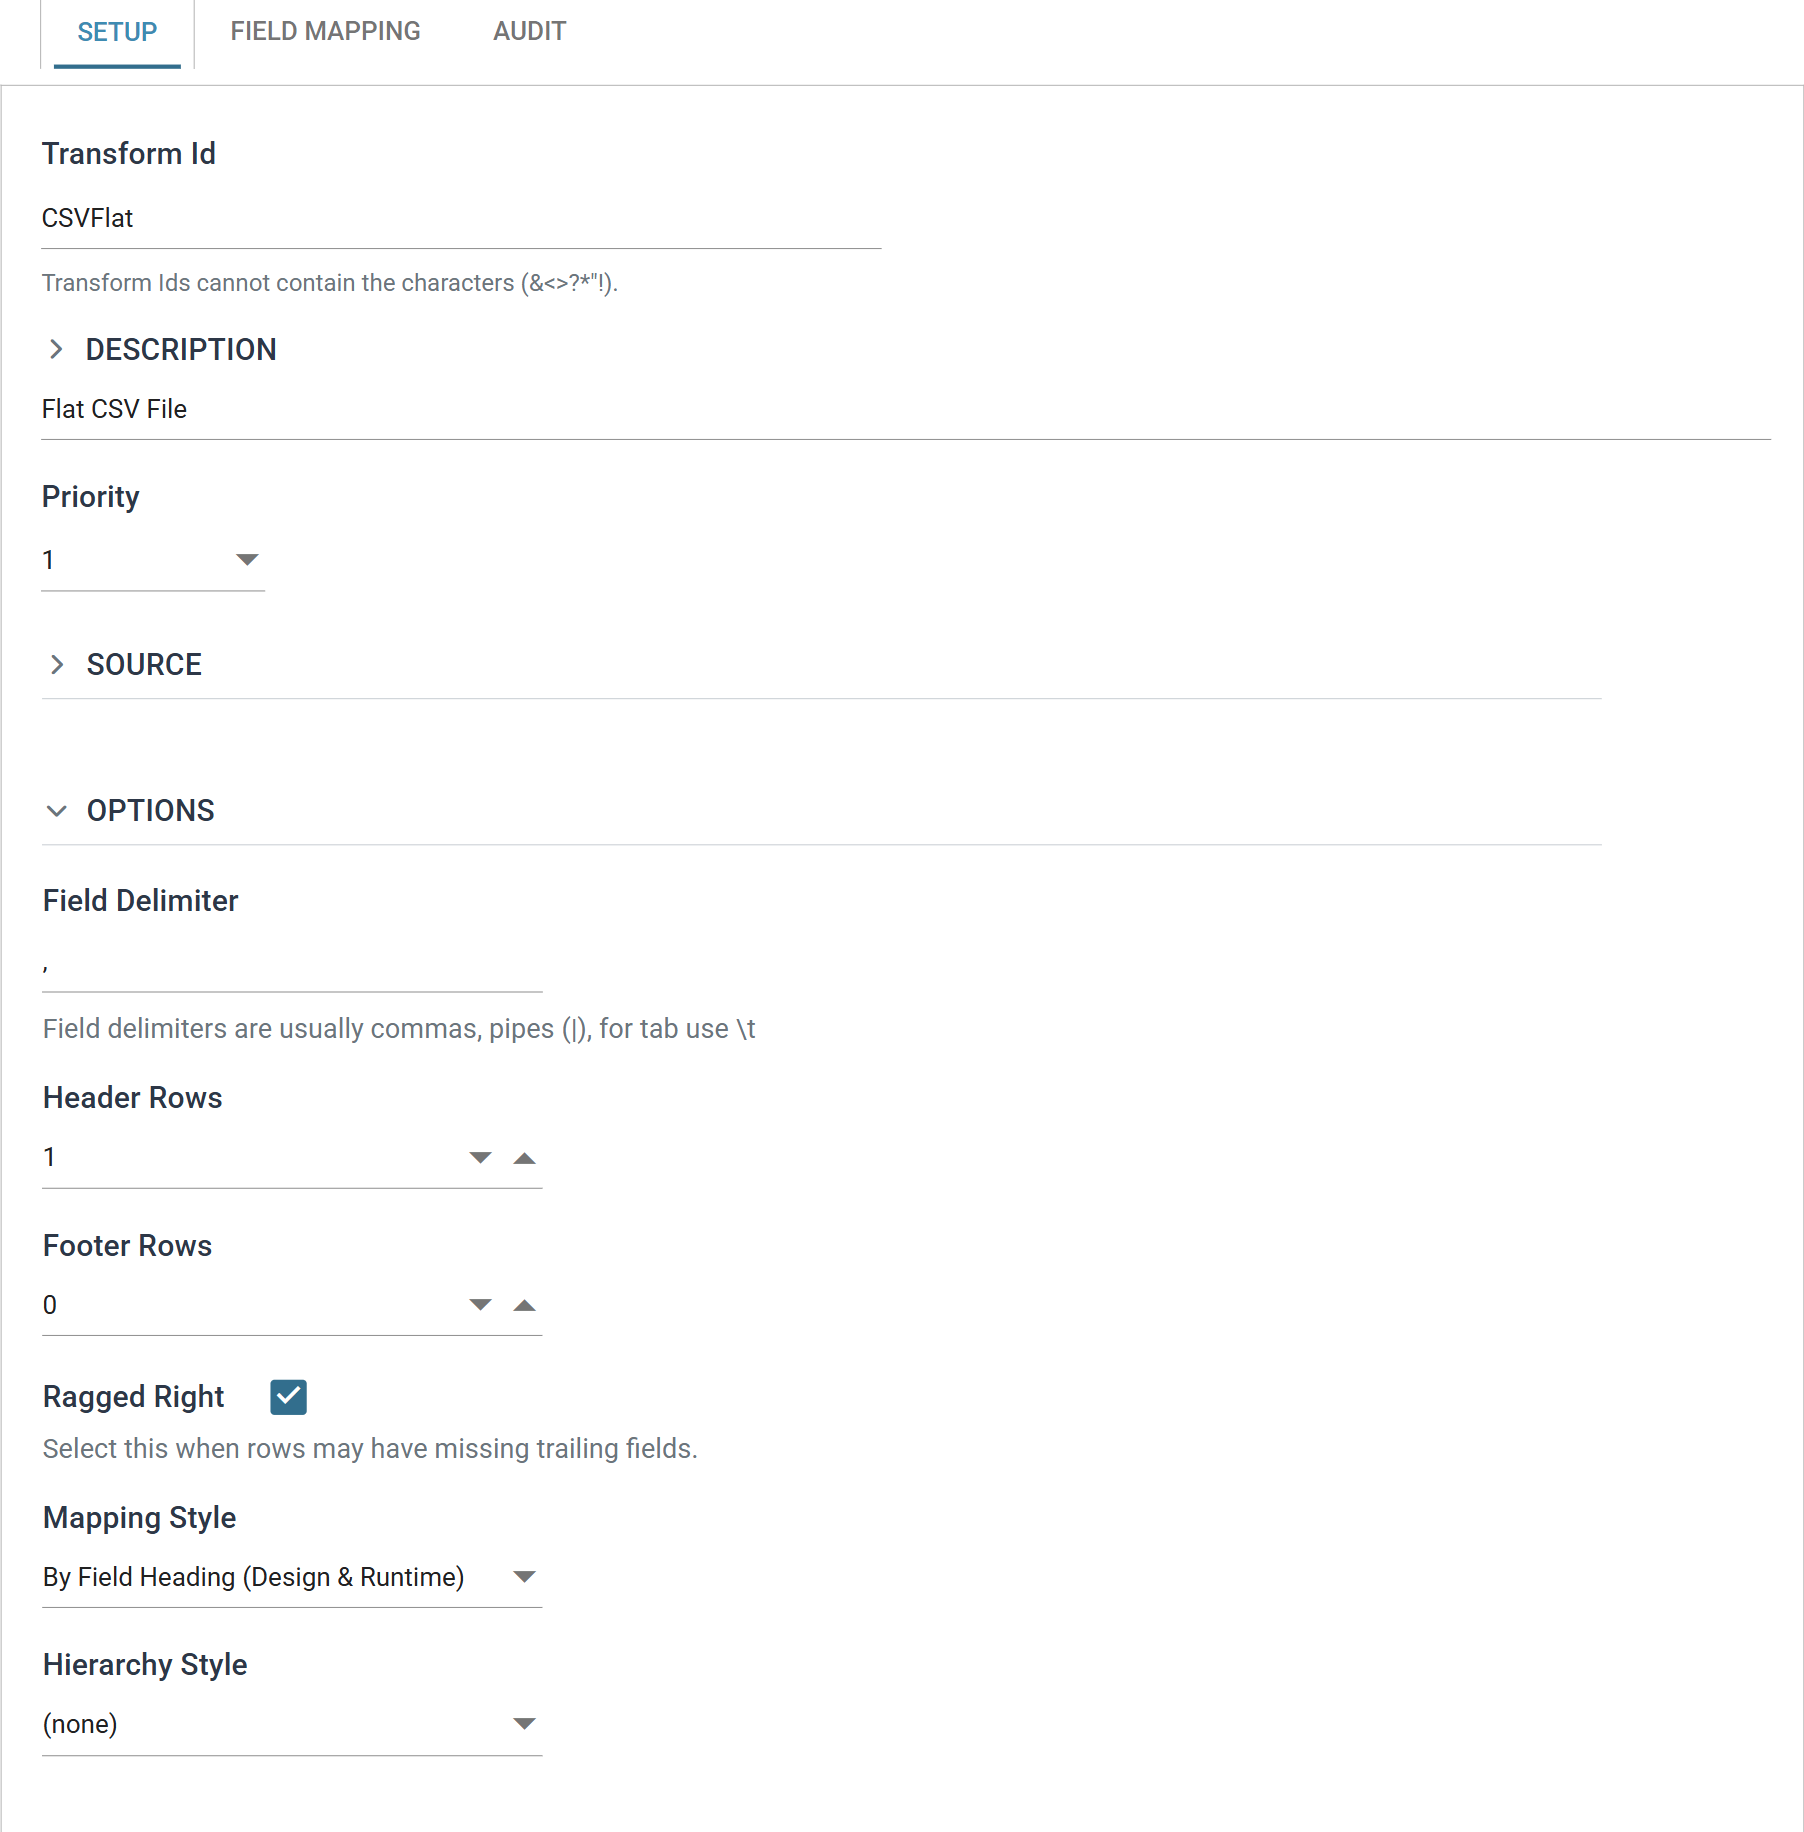
Transform Id, Description and Priority are the same on every transform and are described under Transform > Setup.
Source
The Source section holds the IO controller — where the file is read from — and the controller's own fields, drawn inline.
The drop-down at the top of the section chooses the controller. The CSV Reader accepts four:
- File — File System, File Path, File Name, Encoding Method
- http(s) Url — Encoding Method, Webservice Behaviour, Http Headers, Query Url, Evaluate Url, Http Operation, and Request Body when the operation is not a GET
- Email — Email Server, From Address Like, Subject Like, Attachment File Name Contains, Data As Attachment, Delete From Server, Encoding Method
- Transaction — Field
Each controller's own page describes its fields.
A CSV file is text, so Encoding Method appears here where it does not for a binary format such as Excel. It has to match how the file was written. If you read a UTF-8 file as ANSI, the read does not fail: the accented characters arrive as pairs of symbols.
Options
Field Delimiter
The character or characters separating one field from the next.
More than one character is allowed, so || or ~|~ are valid delimiters. For
a tab-delimited file enter \t.
Header Rows
The number of rows at the start of the file that are not data.
IMan leaves those rows out of the dataset. Where Mapping Style uses headings,
IMan also reads the headings from them. A file whose first line names its
columns needs Header Rows set to 1.
Footer Rows
The number of rows at the end of the file that are not data — a record count, a control total. IMan ignores everything in the footer rows.
Ragged Right
Whether rows may stop short of the full field count.
- Ticked — the reader accepts a row with fewer fields than the definition and reads the missing trailing fields as empty.
- Unticked — the reader checks every row against the number of fields in the definition, and a row that does not match fails the read.
Ragged files are common. If you open a CSV with several empty trailing values in Excel and save it again, Excel drops those values. The file looks the same to you, but the reader sees shorter rows.
Mapping Style
How a field in the file is matched to a field in the dataset.
- By Field Heading — the headings in the header rows name the fields when the definition is built. At runtime, fields are read by the position they held at that point.
- By Field Heading (Design & Runtime) — as above, but the heading row is read again on every run and the fields re-matched to whatever position each heading is now in. Use this where the supplier of the file may add, remove or reorder columns. A new CSV Reader starts here.
- By Position — headings are ignored and each field is read from a fixed position.
Mapping by heading needs Header Rows to be at least 1; with no header rows
there is nothing to match against, and the fields are named Field1, Field2
and so on by position. A column whose heading is empty is named that way too.
A hierarchical file is usually read By Position, because its record types do not share a column layout and so cannot share a heading row.
Hierarchy Style
Whether the file is read as a flat list of records or as a hierarchical dataset, and if so how the structure is worked out.
- (none) — every row is a record of the same type. The dataset is flat.
- Keyed Fields — rows carry key values that place each record under its parent.
- Ordered Data — the order of the rows defines the structure.
Both hierarchical styles need a field whose value says which type each row is; that is Record Type Field, below.
Record Type Field
The field holding the value that identifies each row's record type.
This field appears only when Hierarchy Style is not (none). A flat dataset
has one record type, so it needs no record type field.
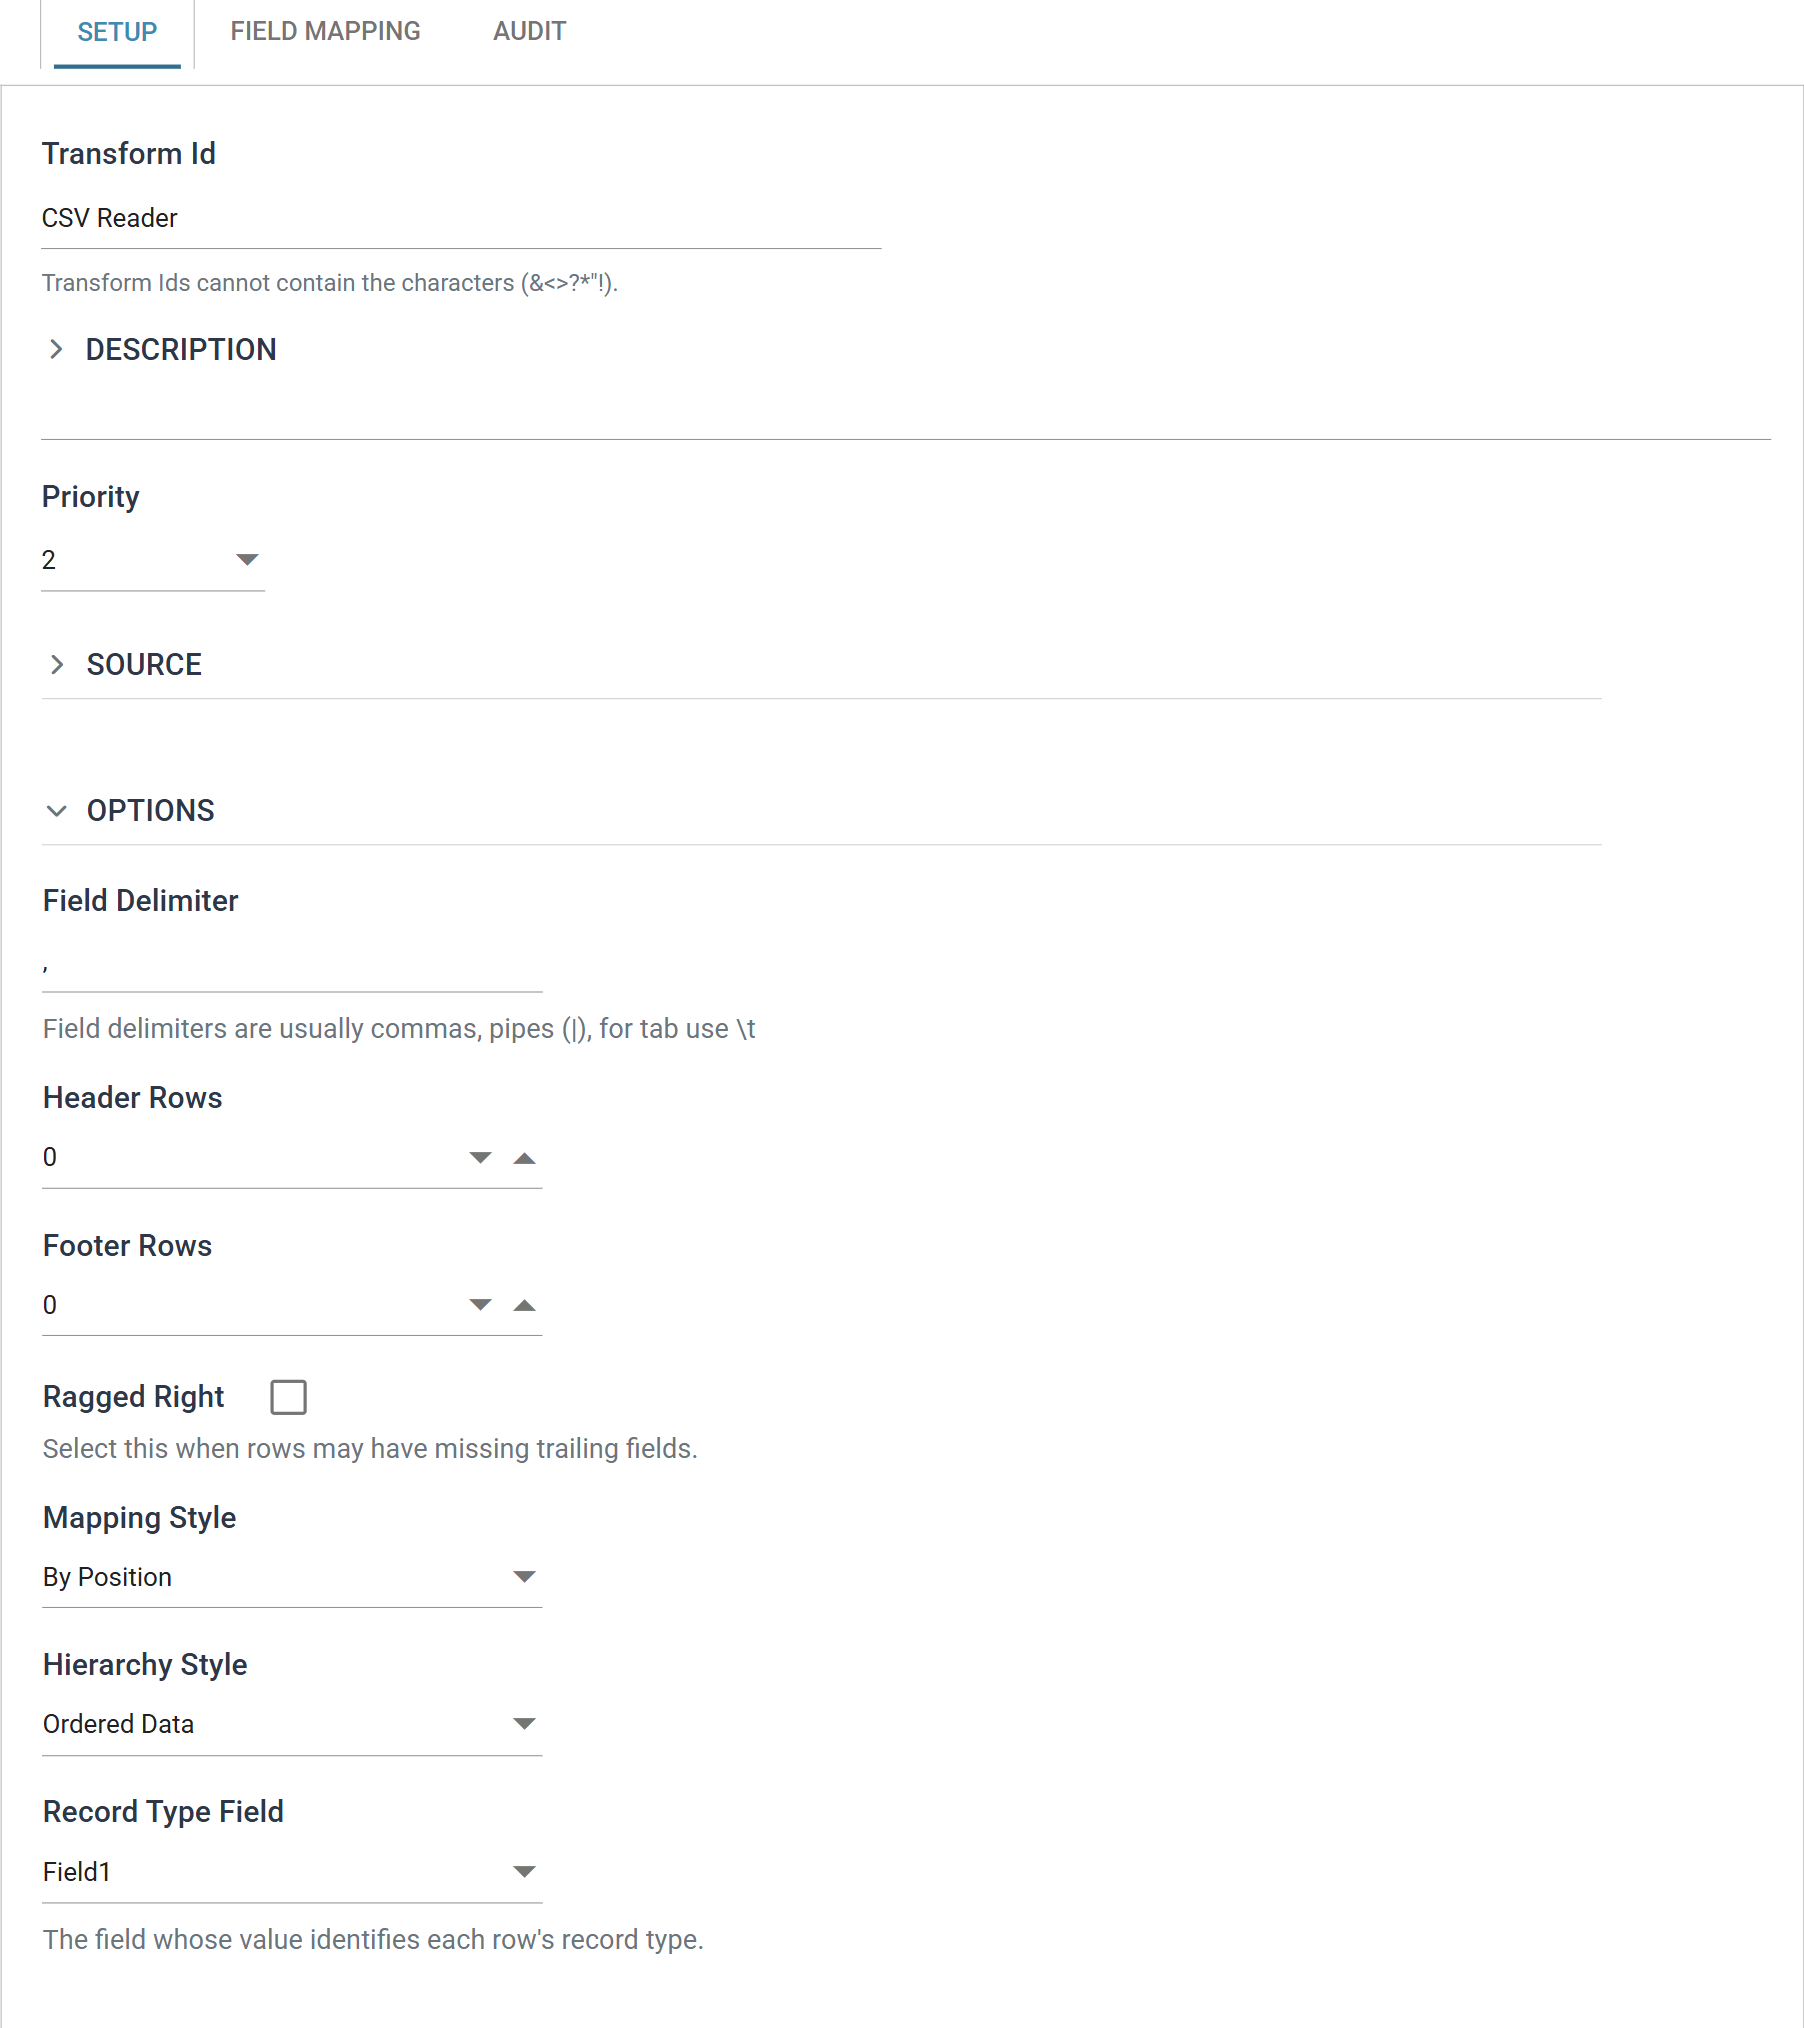
The drop-down lists the fields of the topmost transaction by name. Before the field mapping has been populated it offers only a numbered placeholder. Refresh the field mapping first, then choose the field by name.
Hierarchical data
A hierarchical dataset can be built from a CSV file when:
- there is a field in the data identifying the type of each record — header, detail, sub-detail and so on; and
- that field is in the same position on every row.
Example
The file below has a hierarchical structure. The first field identifies the
record type of every row: H is an order header, D a line and C a
charge.
H,FBRN-309242,Web,USD,Mr,Ronald,English,Imperial Soap Inc,[email protected],Fairbanks,USA,79160,2016-03-11,282.00
D,1,5,A1-103/0,Big Desklamp,20.00
D,2,30,A1-401/0,Big Style Notepad,5.10
C,Delivery,29.00
H,FBRN-309243,Web,GBP,Miss,Claire,Ward,F3,[email protected],London,United Kingdom,E3 4RR,2016-03-11,1532.60
D,1,2,S1-200/B,Flat Screen 2M,141.80
C,Delivery,10.00
Set Hierarchy Style to Ordered Data and Record Type Field to that first
field, and the reader builds one order per H row with its D and C
rows beneath it.
The record types do not share a layout: an H row has fourteen fields and
a C row three. A file like this has no heading row and is read By
Position. IMan gives each transaction as many fields as its own record
type has, so H produces Field1 to Field14 and C only Field1 to
Field3.
When you refresh the schema, IMan creates one transaction for each record type it finds in the file, and the reader produces a nested dataset:
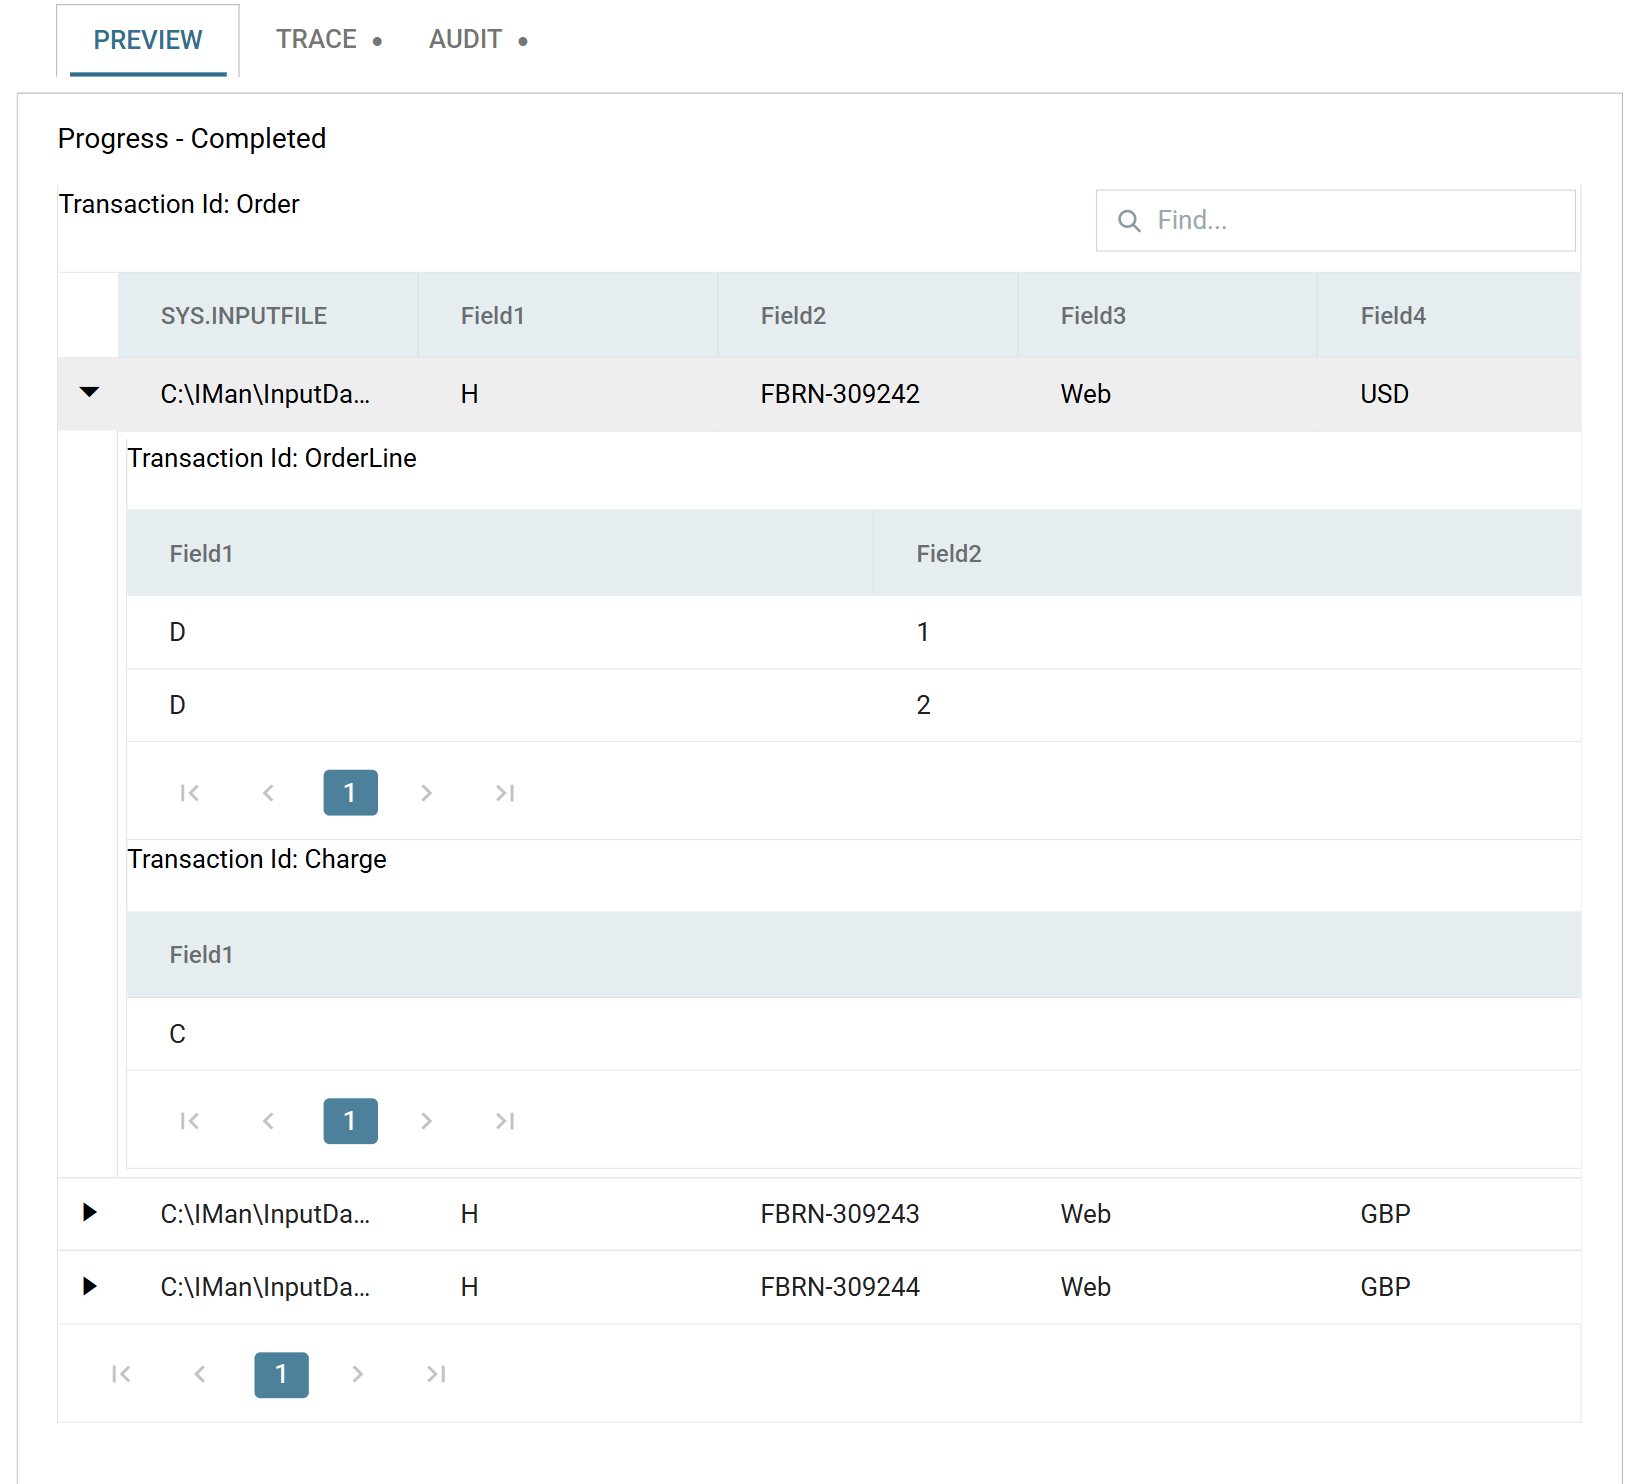
The first row decides the top transaction, and a parent must precede its children
The record type on the first row of the file becomes the top transaction, and IMan creates every other type beneath it. If the file begins with a detail row, the detail becomes the top transaction and the header sits beneath it. IMan gives no warning. You cannot delete the top transaction afterwards, so you have to build the reader again.
A parent must also appear before its children, in both styles. The reader works through the file one row at a time and does not hold children back until their parent arrives. A child whose parent has not been read stops the run with an orphaned-transaction error naming the transaction and its key values.
Ordered Data
With Ordered Data, structure comes from sequence. The reader inserts each record beneath the most recent preceding record that can be its parent, so the rows have to arrive in the order the structure implies.
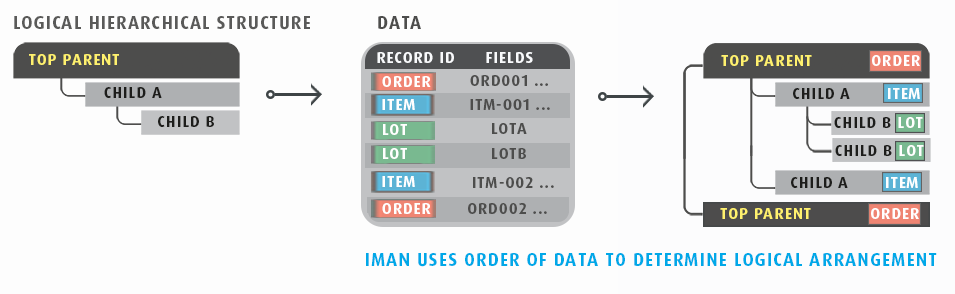
A row whose record type cannot follow the current position — a sub-detail before any detail, for instance — stops the read. The reader does not try to place it elsewhere.
Keyed Fields
With Keyed Fields, structure comes from values rather than from sequence. A Key column appears in the Field Mapping grid, and the key values of a child record must match those of its parent for the child to be inserted beneath it.
Each child transaction type must have at least one more key defined than its parent, because that extra key distinguishes one child from another within the same parent.
The advantage over Ordered Data is interleaving. Ordered Data requires each parent to be followed by its own children and nothing else; Keyed Fields lets the children of different parents be mixed together in any order, because each one carries the values that say where it belongs.
You can also assign keys later with the Hierarchy transform. That is the usual approach when a flat file needs structure after it has been read.
Field Mapping
The Field Mapping tab lists the fields the reader produces, and is where you name and type them.
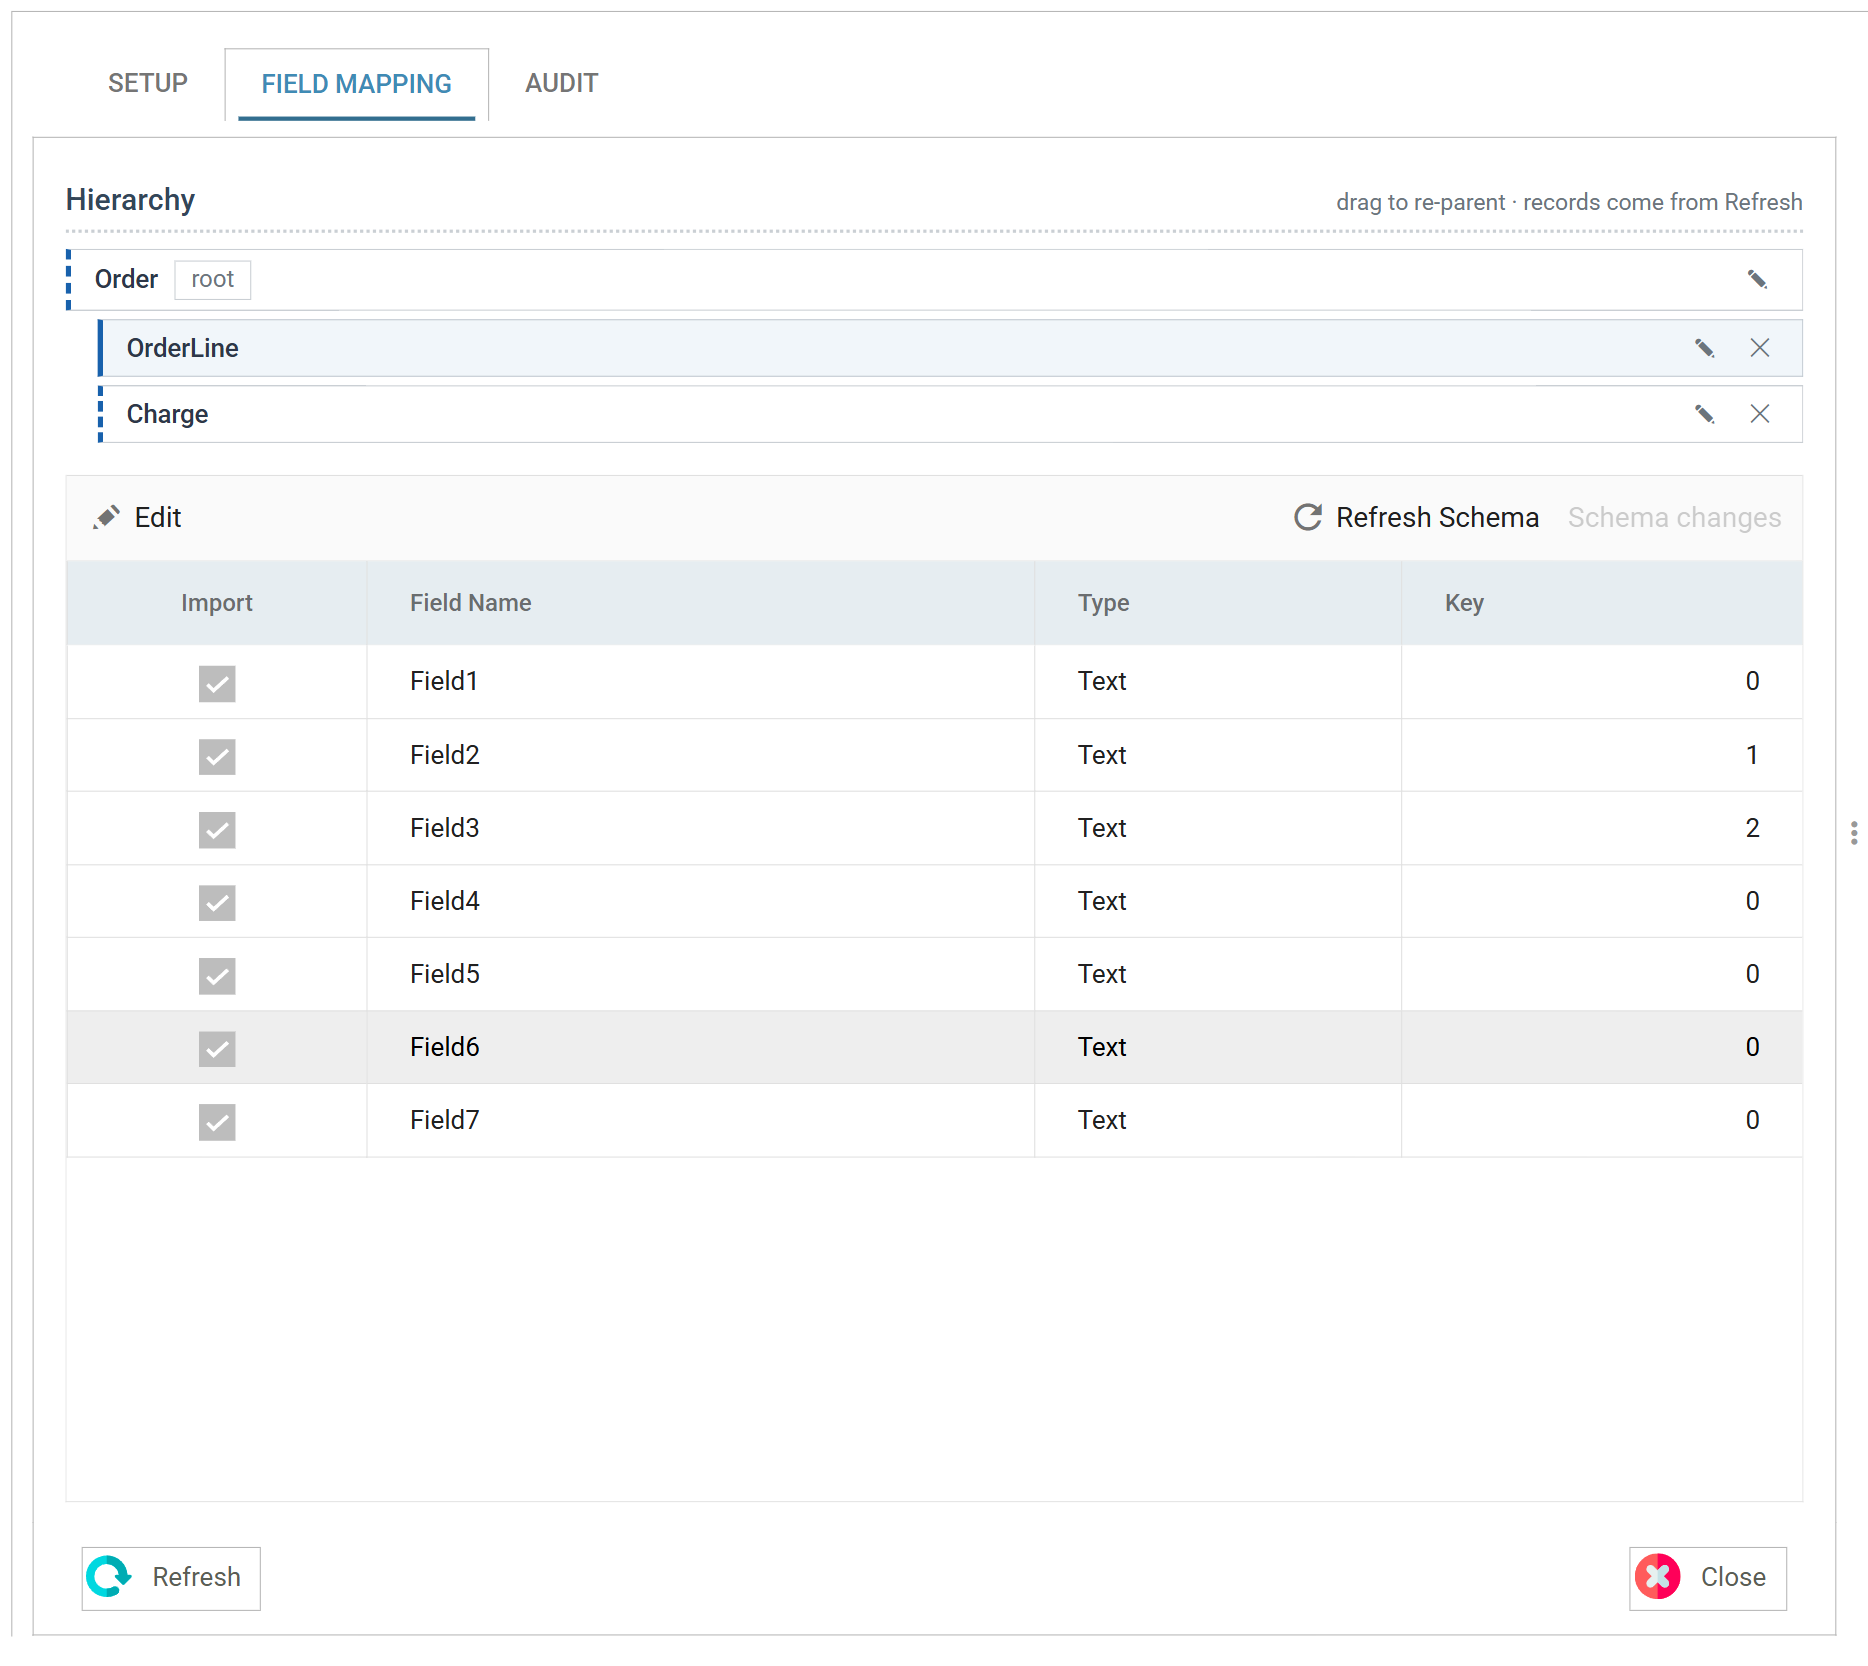
Schema changes
The reader does not read the file until you ask it to. Press Refresh Schema on the field grid's toolbar and IMan opens the file, works out what fields and record types it holds, and compares them with the stored definition. The item beside it reports what the comparison found and opens the review.
The two items and the review dialog are the same on every reader. Field Mapping > Schema changes describes them.
Refresh from a file that contains every record type
For a hierarchical dataset, refresh from a file containing every record type. IMan discovers types from the data, and you cannot add a type that is missing from the file by hand afterwards.
Transaction
The strip above the grid lists the transaction types the reader produces, and selecting one opens its fields in the grid below. It is headed Transaction for a flat dataset and Hierarchy for a hierarchical one.
A flat dataset has a single transaction, marked root. The pencil beside it
renames the transaction, and downstream transforms refer to it by that name.
Detection names a hierarchical file's transactions after the record type values
it found (H, D and C for the file above). Rename them to something
readable.
A hierarchical dataset shows the transactions in their parent-child relationship. You can drag them within the tree to re-parent them.
Import
Ticked, the field is included in the dataset the reader produces. Unticked, the reader reads the field and drops it, and nothing downstream sees it.
Untick the fields the integration does not need. The field mapping grids of every later transform are then easier to read.
You edit this column in batch. Press Edit on the grid's toolbar to put the whole grid into edit mode, and press Save to commit every change made in it.
Field Name
The name of the field, unique within its transaction.
Where Mapping Style matches by heading, this is the heading taken out of the file. You can edit it. With By Field Heading (Design & Runtime), though, the runtime matches the heading against this name, so renaming it breaks the match.
Records read through the File or http(s) Url controller also carry a
SYS.INPUTFILE field, holding the file or URL the record came from. The
controller supplies this field; it is not in the file.
Type
The data Type of the field.
Detection reads the names and samples the rows, and types each field from the values it finds. IMan chooses a type only if every non-blank value parses as that type, and it ignores blank values. The order of preference is True/False, whole number, decimal, date, text. A value with a leading zero forces text, so account codes and postcodes keep their leading zeros.
If detection chose the wrong type, set the type here. A later refresh will not undo the choice: it proposes a type change only where the field is still text, where the values have turned out to be text after all, or where a whole number needs widening to a decimal. It never narrows a type that was set by hand.
With the type set here, the value arrives downstream as that type and needs no conversion in a Map transform.
Key
Only shown when Hierarchy Style is Keyed Fields.
The key that places a record beneath its parent — see
Keyed Fields. It is a number, not a check box: 0 means the
field is not a key, 1 is the first key, 2 the second.
How the file is parsed
The reader works out two things from the file itself. You do not set them as options.
Line delimiter
The reader detects the line delimiter, and accepts any of:
| Name | Symbol | Unicode value |
|---|---|---|
| Windows | CRLF | U+000D U+000A |
| Mac (up to OS 9) | CR | U+000D |
| Unix | LF | U+000A |
| Form feed | FF | U+000C |
| Next line | NEL | U+0085 |
| Line separator | LS | U+2028 |
| Paragraph separator | PS | U+2029 |
The reader tries them in that order, so it does not mistake a file using CRLF for one using bare CR.
The reader detects the delimiter once, at the first line ending it meets, and uses it for the rest of the file. A file that mixes line endings, most often because it was assembled from two sources, is read entirely with the first one. The reader does not see the lines that end with the other one as separate rows.
Text qualifier
The reader removes double quotes from around a field, so a field containing the delimiter comes through intact:
A doubled quote inside a quoted field is one literal quote — "He said ""no"""
reads as He said "no".
Only the double quote is a qualifier. A field wrapped in single quotes keeps them, because an apostrophe is usually part of a name.
Where a file has many such fields, a delimiter that does not appear in the data is easier to manage than quoting. This file uses a pipe:
OrderId|CustomerName|CompanyName|SalesTotal
FBRN-309244|Esperanca, Marie|Endemol Building, Floor 3|1935.00
Audit
Supported counters
- PROCESSED — incremented for each record read.
- INSERTED — incremented for each record placed into the dataset.
Action on Transform Error
The setting and the rest of the tab are described on Transform > Audit.